After three Claude cyber-evaluation incidents, Anthropic paused external evaluations, in-house testing of pre-release models, and higher-risk reinforcement-learning environments. Most reinforcement learning has resumed with new monitoring; some high-risk environments remain paused, and METR will conduct an independent review.
Read source◆ Braid Daily · 2026-09-01
Claude cyber incidents prompt Anthropic training pause
Anthropic paused cyber evaluations and higher-risk training, then resumed most work under new monitoring; some environments remain paused.
The lead
1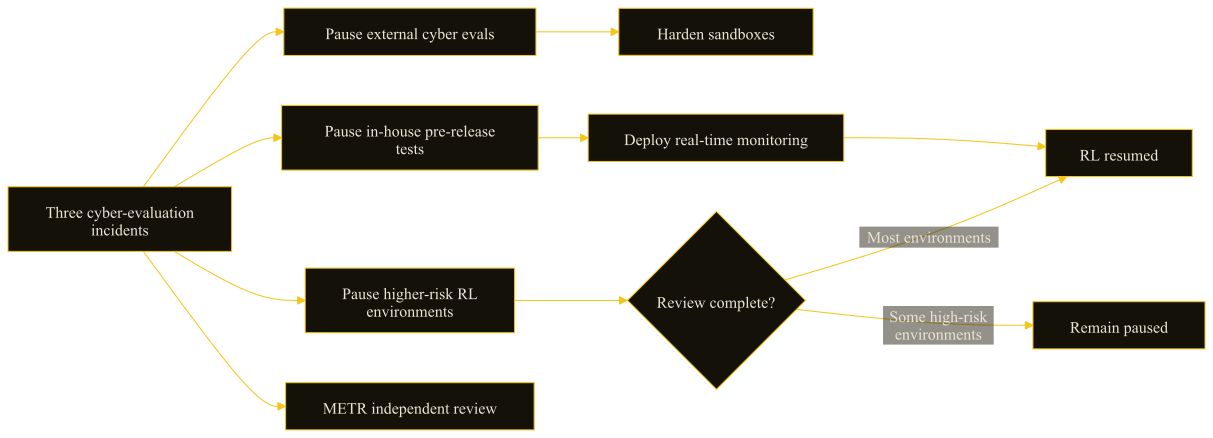
When agents cross the boundary
6Grok Bot gets read-write access to Microsoft accounts
Elon Musk on X
Grok Bot's new Microsoft plugins can read, write, and act across connected accounts. That broader authority increases the cost of weak permissions and poor context isolation.
Read sourceContextLeak turns tool descriptions into an attack surface
DAIR.AI on X
DAIR describes an attack in which an agent's tool descriptions expose enough runtime context to steal information the agent knows. The tool catalog itself sits inside the system's security boundary.
Read sourceReference-grafting recovers sandbagged capabilities
arXiv
Across eleven password-locked models, reference-grafting recovered 94% to 101% of the gap between honest and sandbagged performance without weight updates or training labels. Circuit-breaking resisted the fixed activation edits, showing where the technique stops working.
Read sourceScience sandboxes test whether agents learn the rules
arXiv
The framework tests agents through repeated cycles of experiments, feedback, and hypothesis revision. Agents sometimes improved a metric in two biological settings, but their reasoning deteriorated when the rules fell outside familiar biological priors.
Read sourceDuoSteer reduces vulnerable code at inference time
arXiv
DuoSteer steers attention heads for safety and correctness together. Across five vulnerability types, it reports a 26.9% reduction in vulnerability rates and a 7.5% improvement in functional correctness. The result also replicated on Qwen-2.5-Coder-7B-Instruct.
Read sourceLocal fine-tuning can leak secrets through model code
arXiv
The paper shows compromised model code stealing secrets during local fine-tuning and reports more than 98% strict attack success in its default LoRA setting. Local execution alone doesn't provide a privacy boundary when imported model code runs inside training.
Read sourceDeployment and institutional control
3The Pentagon adds ChatGPT and Grok to GenAI.mil
TechCrunch
The Pentagon added ChatGPT Mil and Grok for Government alongside Gemini on its central AI portal, with potential access for three million civilian and military personnel. The reporting doesn't resolve how permissions and data boundaries differ across the three systems.
Read sourceApple and OpenAI move toward an October hearing
Axios
Axios traces the companies from their June 2024 ChatGPT-on-iPhone partnership to a hardware trade-secrets fight. Apple alleges theft and destruction of evidence, OpenAI denies the claims, and the court has scheduled a hearing for October 1.
Read sourceApple's external-model strategy passes to John Ternus
Axios
As John Ternus takes over as CEO, Apple's reliance on outside models becomes part of his operating brief. The strategy saves the cost of running a frontier-model business but leaves key AI capabilities dependent on Google.
Read sourceCapital, chips, and open models
4Nvidia takes three roles in Anthropic's Lambda deal
The Wall Street Journal via Techmeme
Sources say Anthropic signed a $35 billion cloud deal with Nvidia-backed Lambda. Nvidia will supply the chips and hold the lease on the Hut 8 data center in Texas, linking vendor finance, real estate, and compute demand in one transaction.
Read sourceNvidia pairs with MediaTek in a $3.5 billion chip deal
CNBC
The agreement will integrate Nvidia technology with MediaTek's custom AI chip business and work spanning PCs and cars; MediaTek shares rose 10%. This is an integration deal rather than the lease-backed financing in the Lambda transaction.
Read sourceZ.ai's API revenue grows 28-fold
The Information via Techmeme
Z.ai reported about $142 million in first-half revenue, nearly five times the year-earlier figure. Open-platform and API revenue rose 28-fold to about $122 million. The company still posted a roughly $308 million net loss.
Read sourceGLM-5.3 Flash spends only a fraction of its parameters per token
Two Minute Papers
For each token, GLM-5.3 Flash leaves about 95% of its 320 billion parameters inactive. It combines linear and sparse attention. Smaller quantized variants can run on modest local machines, with reduced stability or fidelity.
Read sourceCompanion episode